The problem with asking a chatbot for references
Here is a simple experiment any student or researcher can run. Open a general AI assistant and write something like: “Give me the most important studies on this topic, with the researchers’ names, the year of publication and a link.”
In many cases you will get an answer that looks excellent at first glance. An ordered list, convincing academic titles, researcher names that look real, well-known journal names, plausible years, perhaps even a short summary of each study.
Tired of juggling ten tabs? ToolSuite bundles the AI workflow tools power users rely on — in one place.
Try ToolSuite NowThen you go looking for one of those papers.
You cannot find it.
You try the full title in Google Scholar. Nothing. You search by author and title. Nothing. You search the journal’s own site. Nothing.
The problem here is not simply that the AI “got a fact wrong”. The problem is that the reference itself may never have existed.
This is one of the most dangerous failure modes of language models, because the error arrives in such a convincing form. The model does not usually tell you it is unsure. It can construct a reference that looks entirely reasonable, because its core job is to produce text that is linguistically plausible — not to guarantee that every paper it mentions actually exists.
So handling AI properly in academic research does not start with the question: “How do I write a better prompt so it gives me correct references?”
The better question is: how do I design a workflow in which inventing references is unnecessary in the first place?
And the answer is fairly simple:
Use search tools to find real sources, then use AI to help you read, understand and compare those sources.
That small difference in method changes a great deal.
Why do fabricated references look real?
Language models are very good at recognising patterns.
If you ask one to write an academic reference, it knows what an academic reference usually looks like: one or more author names, a study title, a journal name, a year, a volume, an issue, perhaps pages and a DOI.
But knowing the shape of a reference is not the same as knowing that the reference exists.
That is where the problem happens. The model may combine a real researcher, a real research topic, a real journal and a plausible year, and produce from them a reference that journal never published.
It is not limited to journal articles either. The same can happen with books, government reports, institutional pages, studies, statistics and even links.
For that reason, a reference list produced by a chatbot should not be treated as a ready-to-use source list. You can use it as a starting point, or as suggestions for keywords, researcher names and topics — but the existence of every source must be verified independently before you cite it.
The most important rule here:
If you cannot open the source and read it yourself, do not treat it as a source.
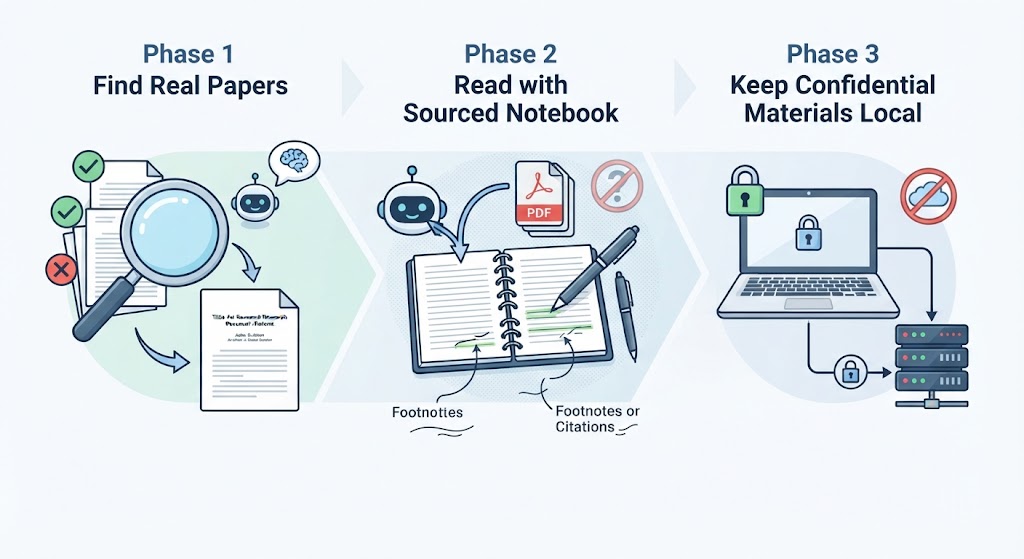
Step one: find real papers
Instead of asking a language model about the papers it “remembers”, start from a search engine or a database that actually holds records of published research.
This is where tools like Semantic Scholar matter. The platform is not merely a traditional search engine; it applies AI and machine learning to help a researcher deal with a large volume of scholarly literature.
It is especially useful at the initial triage stage.
Rather than opening dozens of papers one after another to find out whether they are worth reading, you can use the information available about each one to form a first impression. The short TLDR summaries, for instance, help you grasp a paper’s topic quickly.
But more important than the summary is the scholarly context around the paper.
A paper existing in a database does not automatically mean its findings are settled fact. It may be an important study, or a preliminary one, or one whose results are contested, or one that later research contradicted.
This is where citation information becomes very valuable. Instead of only asking:
“How many papers cited this study?”
it helps to ask:
“Why did those papers cite it?”
You may find one study was cited in support of its findings, while others cited it to point out a methodological problem or to discuss a result that did not replicate. That is a large difference. Citation count alone may suggest a paper’s prominence, but it does not necessarily tell you how strong any individual finding within it is.
Do not start by reading everything end to end
A common mistake in academic research is downloading dozens of papers and then trying to read them all in sequence. That becomes exhausting very quickly, particularly in fields publishing large numbers of studies.
A staged process works better:
- Search for studies related to the topic.
- Read the title and abstract.
- Check the publication year and the method, briefly.
- Look at the citations and related sources.
- Select a smaller set of important papers.
- Download the full texts you actually need.
- Only then use AI to help you analyse them.
This way AI is not responsible for choosing “the truth” on your behalf. It becomes a tool helping you work through a set of sources that you found. That is far safer.
Step two: read with a source-grounded assistant
Once you have gathered a set of real PDFs, the nature of the task changes completely.
You are no longer asking the AI:
“What does the research say about this topic?”
You can now say:
“Here are five studies I found. Compare them.”
That is a fundamental difference.
You can upload the papers to NotebookLM, for example, and use it to work through the sources you placed in front of it. The important property is that the conversation becomes tied to a defined set of documents, instead of the question being open to whatever knowledge the model may claim to hold.
That makes far more useful questions possible. Instead of “summarise this study”, you can ask:
- What research question was the study trying to answer?
- What was the sample size?
- How were participants selected?
- What method was used?
- What are the main findings?
- What limitations did the researchers state?
- Do the results establish causation, or only correlation?
- Are there findings that conflict with another study?
- Where do the researchers differ in interpreting the results?
- Which claims are not directly supported by the data?
- What did the study not test at all?
These questions are worth far more than asking for a one-paragraph general summary.
Do not make summarising the main goal
Summarising is one of the most common uses of AI, but it is not necessarily the most useful in research.
If a paper runs to twenty pages, it is relatively easy to ask a model to compress it into one. But the harder and more important question is:
What does this paper say compared with the others?
Imagine you have read five studies on the effect of a particular technology. Each might say something that sounds similar: “the study found a positive effect.” But on closer inspection you may discover that:
- The first used a very small sample.
- The second used data spanning several years.
- The third studied a different age group.
- The fourth found only a correlation, not a causal relationship.
- The fifth found no statistically significant effect.
If you ask the AI to summarise each study separately, you may get five good paragraphs and still have to find the differences yourself. Give it all five and ask it to compare them, and the tool becomes considerably more useful.
You might ask, for instance:
“Build a table comparing sample size, method, time period, the variables measured, the main finding and the limitations for each study.”
Here the AI is not acting as an author of references. It is acting as a research assistant, helping you organise a volume of information that might take you hours to compare by hand.
Read the citation, not just the answer
Even when using a source-grounded tool, do not treat the answer as final.
If the system tells you “the study found that factor X increases factor Y by a certain percentage”, do not stop at that sentence. Open the citation and go to the original passage in the paper.
The stated result may well be correct while the context is different. The figure may apply to a particular subgroup, or to a secondary outcome, or to one specific statistical model. There may be a sentence immediately after it explaining that the result was not strong enough to generalise.
This is why citations matter so much. They move verification from:
“Do I trust the model?”
to:
“Can I check what the model said against the source?”
The second question is far easier to answer.
Step three: keep confidential material local
There is another dimension here, and it has nothing to do with accuracy. It is privacy.
Not every document is appropriate to upload to a cloud service. You might be working on:
- Internal company documents.
- An unpublished study.
- Client data.
- Material covered by a confidentiality agreement.
- Proprietary source code.
- Internal financial reports.
- Research or results not yet announced.
- Documents containing information you have no authority to share with an external service.
In those cases you should ask a different question: should this data leave my machine at all?
If the answer is no, running a model locally may be the better option. LM Studio offers a relatively easy way to run language models on your own device, and our guide to running AI models on your own computer walks through the process step by step.
But running a local model does not suddenly make it as capable as the best cloud models. On an ordinary machine you may be using a relatively small model, possibly weaker at some complex tasks, and processing speed may be limited by your CPU, memory and graphics card.
Even so, there are cases where maximum model power is not the priority. If the document must not leave the organisation, then privacy becomes part of the requirements of the solution itself — and a smaller local model can be more useful than a stronger one you are not permitted to use with your data.
Local AI is not a magic answer either
It is important not to fall into the opposite trap. Running a model locally does not mean everything is automatically safe or correct.
The model can still make mistakes, misread a passage, or infer something that is not in the document. The essential difference is that the data stays within an environment you control — not that the model has become infallible.
So the rule stands: source first, model second.
Working in Arabic: a source problem and a language problem
Working in Arabic introduces an extra difficulty.
Arabic-language scholarship is not always represented in international academic indexes to the same degree as English-language work. That means searching only in Arabic may cut you off from a large part of the existing studies.
Even when the research topic concerns the Arab world, studies published in English may be more numerous or more visible in international academic databases.
So in many cases it helps to search in both languages. Start with the Arabic term, then look for the English equivalent of the same concept. Sometimes you need more than one phrasing of a term, because researchers may use different terminology for the same idea. This step looks trivial, and it can change your search results substantially.
What about using AI in Arabic?
Once you have gathered the sources, AI takes on another role: reading and writing in Arabic.
If you are reading English research and want to turn your understanding into Arabic notes or a report, language models can save a great deal of time.
But even here, watch the terminology. A literal translation is not always the best academic translation. Some scientific terms have a common rendering and a literal one, and choosing the wrong term can change the meaning.
It therefore helps to know what the Arabic models can do and where they are heading — see Arabic AI models: who is actually building them. Fanar can be useful in this context in particular, when the priority is handling Arabic content.
But even with a good Arabic model, the basic rule does not change:
Do not let the quality of the language fool you about the quality of the source.
Excellent Arabic prose does not mean the information is correct. Convincing academic phrasing does not mean the reference exists.
What to do if a chatbot hands you references
You do not need to throw the whole list away. You can use it as an initial map.
If the model names a study with a particular title, search for it in an academic database or on the publisher’s site. If you find it, open it and verify:
- The title.
- The authors.
- The year of publication.
- The journal or conference name.
- The DOI, if there is one.
- The link.
- The content of the study itself.
If you cannot find it, do not try to “fix” the reference by guessing. There may be an error in the title, the author’s name or the year — but the reference may equally be entirely fabricated. The safer approach is to treat it as unreliable until you find the real source.
Do not trust a DOI just because it looks right
There is another trick that makes fabricated references more convincing: adding a DOI.
A reference containing a long string of letters and numbers can look more authoritative, but the presence of a DOI in the text does not mean the DOI is valid. If you are going to use it, check it properly.
The same applies to article links. A link that looks like a journal link may not lead to the study the model claims. It is not enough for a link to have the right shape. It has to open the right source.
Separate three different things
While researching, it helps to distinguish between:
1. Finding the source
This is the job of search engines, databases and scholarly indexes. Its purpose is to locate studies that genuinely exist.
2. Understanding the source
This is where AI comes in. It can help you read the text, extract the important points, compare studies and explain terminology.
3. Judging the source
This is the hardest stage, and it should not be delegated wholesale to a model.
Is the method sound? Is the sample adequate? Are the results generalisable? Is there a conflict of interest? Does later research contradict the findings? Is the conclusion the researchers reached genuinely supported by the data?
These questions need critical thinking, not a summary.
A practical workflow you can repeat
If you are writing a paper or a report that rests on scholarly sources, you can follow a simple sequence:
Stage one: search. Define the question precisely, then look for studies using search engines and academic indexes.
Stage two: filter. Do not collect everything that appears. Choose the studies most closely tied to the question.
Stage three: verify. Confirm that each study exists, along with its basic details.
Stage four: get the full text. When a study genuinely matters, obtain a copy you can read and return to.
Stage five: analyse with AI. Put the set of studies in front of a tool that works on sources, then ask for comparison, analysis and extraction.
Stage six: check by hand. When the model gives you an important piece of information, go back to the original text.
Stage seven: write. Cite the source itself, not the chatbot’s answer.
Done this way, AI becomes a layer of assistance on top of the research process rather than a substitute for it.
What if you are in a hurry?
Being short of time is not a reason to skip verification. If anything, the opposite: when you are rushed, source-grounded tools become more important, not less.
Instead of reading fifty full papers, you can identify ten likely ones and use a document-analysis tool to extract:
- The research question.
- The sample size.
- The method.
- The main findings.
- The limitations.
- The data used.
- The differences between studies.
Then you choose which papers need deeper reading. That saves time without turning the model into a source of information.
The biggest mistake: making AI the last link in the chain of sources
There is a large difference between saying:
“The AI found that the study says X.”
and saying:
“The study itself found that X.”
In academic work the difference is not merely linguistic. In the first case you are relying on an intermediate interpretation that may have been wrong. In the second, you can return to the source and demonstrate what you wrote.
This is why the best use of AI in research is not to let you dispense with sources, but to make you better able to work with them.
The rule underneath all of this
Everything above reduces to one rule:
Never let the model be the source. Let it be the reader.
Use it to read alongside you. Use it to help you understand a long paper. Use it to compare five studies. Use it to find contradictions between findings. Use it to extract information from dozens of pages. Use it to explain a difficult term. Use it to turn your notes into an organised draft.
But when you reach the sentence you are going to put in your work — the one that says “study X showed that…” — you should know where that study is, be able to open it, read the part you are relying on, and confirm that your sentence does not go beyond what the study actually established.
There is also an important difference between a source existing and a source supporting the claim. The paper may genuinely exist, the title may be correct, the researchers may be real, and it may still not be evidence for the sentence you want to use it for.
So it is not enough to ask:
“Does this reference exist?”
Ask also:
“Does this reference actually say what I am claiming it says?”
That extra step is what separates using AI as a useful research tool from using it as a machine for producing academic-looking references.
In the end, AI can remove many hours of work, but it does not remove the need for the original source. If anything the reverse is true: the better models become at producing convincing text, the more important our ability to verify the original source becomes.
Search first. Verify the source. Read it. Then let AI help you understand it.
The source is the evidence; AI is the assistant. Do not reverse the equation.


Comments
0No comments yet.
Please log in to comment.
Comments are available for members only. Sign in to participate in the discussion, or create a new account for free.